
Phoenix-4.5: A New State of the Art in Real-Time Human Rendering
Phoenix-4.5 is the fastest and most expressive real-time human rendering model on the market, and the closest AI has ever come to passing the Turing test face to face. The whole PAL moves with every word, in 134 ms from audio to video.

Griffin: The First Human Interaction Model

Griffin is the world’s first Human Interaction Model. It sees you, hears you and talks back, all at the same time. Not a chain of systems taking turns, but one model in one conversation: it nods along, cuts in, gives you room to think. After a one-minute video call with it, not knowing what it was, 48% of people believed they’d been talking to a real person.
Research
Interactive avatars in enterprise: how to build trust at scale
Interactive avatars for enterprise build trust through behavioral realism, precise conversational timing, and closed-loop perceptual AI. Here is how it works.
Research
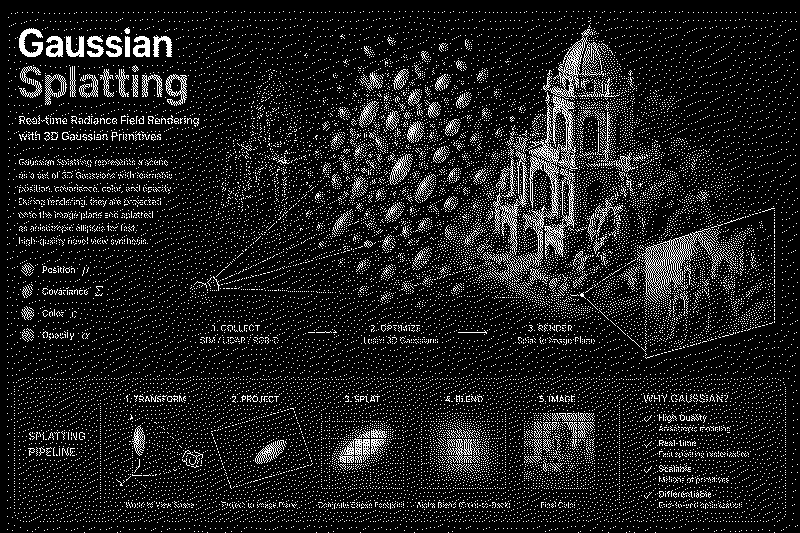
Gaussian Splatting From Scratch: Explained Through Code
I built a minimal Gaussian Splatting implementation in pure PyTorch to understand how it actually works. This post goes through that code and explains what each piece does, why it’s there, and how it all fits together.
Research
AI faces: how they're generated, animated, and used
Modern AI faces can hold live conversations and read your expressions. Explore the rendering, turn-taking, and perception models that make it possible.
Research
Face-to-face conversational AI vs. chatbot: understanding the full spectrum
The face-to-face conversational AI vs. chatbot comparison comes down to capability tiers. A guide to types, examples, and when to move from text to video.
Research
Customer service training: AI video agents for realistic practice
Discover how AI video agents transform customer service training with realistic practice. Learn implementation strategies, benefits, and real-world applications.
Research
Conversational AI for healthcare: Building HIPAA-compliant patient video conversations
Conversational AI for healthcare is evolving beyond chatbots. Learn how to build HIPAA-compliant patient video conversations with real-time AI Personas.
Research
Learnings From Random LoRA-Finetuning Experiments On A Guided Music Synthesis Diffusion Model
A hands-on experiment fine-tuning ACE-Step v1.5, an open-source AI music generation model, to fix its garbled lyric problem using LoRA and Attention Sharpness Regularization. What started as a random Friday night side project turned into a deep dive into how a 2-billion-parameter diffusion transformer actually processes text, and what breaks when you try to change it.
Research
Raven-1: Bringing Emotional Intelligence to Artificial Intelligence
Introducing Raven-1. A multimodal perception system that captures not just what users say, but how they say it, how they look when they say it, and what that combination actually means. It interprets tone, expression, hesitation, and context in real time, enabling AI that can truly understand intent rather than simply respond to words.
Research
Sparrow-1: Human-Level Conversational Timing in Real-Time Voice
Sparrow-1 is a specialized, multilingual audio model for real-time conversational flow and floor transfer. It predicts when a system should listen, wait, or speak, enabling response timing that mirrors human conversation rather than simply responding as fast as possible.
Research
From random noise to real images: Understanding loss-function formulation
From theory to code: how diffusion and flow matching models turn Gaussian probability paths into vector fields, training targets and practical loss functions.
Research
Understanding intuition behind multi-turn LLMs through the prism of search
Discover the latest research in how LLMs use reinforcement learning to search, reason, and refine answers across multiple turns—boosting accuracy and enabling active problem-solving.
Research
Anam AI vs Tavus: feature comparison and explanation
Choosing between Tavus and Anam comes down to one question: do you need an AI persona that can talk, or an AI human that can genuinely understand the person in front of it? This piece covers where the two platforms differ on emotion control, active listening, and perception, what that difference looks like in real-world conversation, and what an independent paired evaluation of 80 sessions found when users experienced both side by side.
Research
Hummingbird-0: Advancing Zero-Shot Lip Synchronization in AI-Generated Video

We made an unexpected discovery while developing our premium conversational AI technology. Components of our advanced video pipeline could be isolated and explicitly optimized for lip synchronization, with remarkable results. This serendipitous research byproduct evolved into Hummingbird, a specialized zero-shot lip-sync model that achieves state-of-the-art performance compared to other leading solutions.
Research
Sparrow-0: Advancing Conversational Responsiveness in Video Agents with Transformer-Based Turn-Taking
In this paper, we dive into the development and research behind Sparrow-0, exploring the innovative transformer-based approach for turn-taking and its integration alongside Raven and Phoenix models within our Conversational Video Interface (CVI), an end-to-end operating system designed for building responsive video agents.
Research
Phoenix-2: Advanced Techniques in Talking Head Generation — 3D Gaussian Splatting
This paper will cover the past, present and future of the talking-head generation research field. Specifically, we will dive deep into the trending 3D scene representations (NeRF -> 3DGS) and the benefits of employing 3DGS in avatar applications.
Research

Phoenix-1: Realistic Avatar Generation in the Wild
This research paper, written by the Tavus team, details the development of Phoenix, a groundbreaking generative model for realistic avatar creation and text-to-video generation. Phoenix leverages audio and text-driven 3D models, integrating volumetric rendering techniques and 2D Generative Adversarial Networks (GANs) to create lifelike replicas from short video clips.
Research